How to Evaluate a Deepfake Detection API: A Reproducible Pilot
A working API request is only the first test. This protocol helps a team evaluate the files it actually receives, keep uncertainty visible and decide which findings deserve review.
Define the decision before collecting scores
Choose one intake task: claim photos, marketplace listings or another repeated image submission. Write down the question the image analysis can answer and the action a reviewer could take. An AI-generation signal may justify closer inspection; it does not establish fraud, ownership, identity or whether a claim should be paid.
Keep integration testing separate from evaluation of real media. The free sandbox returns fixed examples and exercises request, status and webhook handling. It does not analyse the uploaded file. Live checks require billing and a spending limit; completed inconclusive reports are billable, while processing failures are not.
Build independent labels, not a collection of favourable results
For genuine-source controls, retain the camera or publication history you can support independently. For generated controls, retain the generator, creation date and relevant settings when available. A believable appearance, a missing credential or another detector’s verdict is not sufficient ground truth. Keep disputed or partly edited material in a separate group with its uncertainty stated.
Include the subject matter and delivery conditions found in your actual intake. Product photos, portraits, damage photos and document screenshots have different content. Test their groups separately before combining results. The research by Ojha, Li and Lee studies the difficulty of generalising to generators absent from training; its reported performance belongs to that paper, not to DeepfakePolicy.
Use a development set to choose any review threshold, then freeze it before reading the held-out evaluation results. Do not move the threshold after seeing test labels and call the same set an independent evaluation. A small pilot can expose obvious workflow failures; it cannot establish a reliable population error rate.
- Record who supplied the source label and what evidence supports it.
- Keep uncertain origin and altered genuine photos distinct from fully generated images.
- Separate related versions of the same source family from independent examples.
- Keep permission to process the files and remove unrelated personal material before the pilot.
Preserve one exact file identity for every input
Record the filename, byte size, dimensions or duration, and SHA-256 before processing. A hash identifies the bytes you submitted; it does not establish their truth. Keep the original and every derivative as different inputs. A resized copy, JPEG recompression or screenshot should have its own hash and a documented transformation.
The evaluation worksheet includes source_family and variant fields so related copies can be inspected together without inflating the count of independent examples. Apply the same transformation to genuine-source and generated controls. Keep the actual image format and source.name consistent with the API contract.
For a local file, run sha256sum filename.jpg on Linux, shasum -a 256 filename.jpg on macOS, or Get-FileHash filename.jpg -Algorithm SHA256 in PowerShell. Hash the submitted bytes again if your application transforms them before upload.
| Condition | Record before submission | Question to examine |
|---|---|---|
| Preserved original | Source, size, dimensions and SHA-256 | Does the workflow handle the clearest available input? |
| Resized copy | Target dimensions and resize settings | Does your normal upload transformation change the finding? |
| JPEG recompression | Quality setting and output SHA-256 | How does your delivery copy behave compared with its source? |
| Screenshot | Capture method and resulting dimensions | Is the low-quality copy still useful, or should the reviewer request the original? |
Inspect a real recorded control without turning it into a benchmark
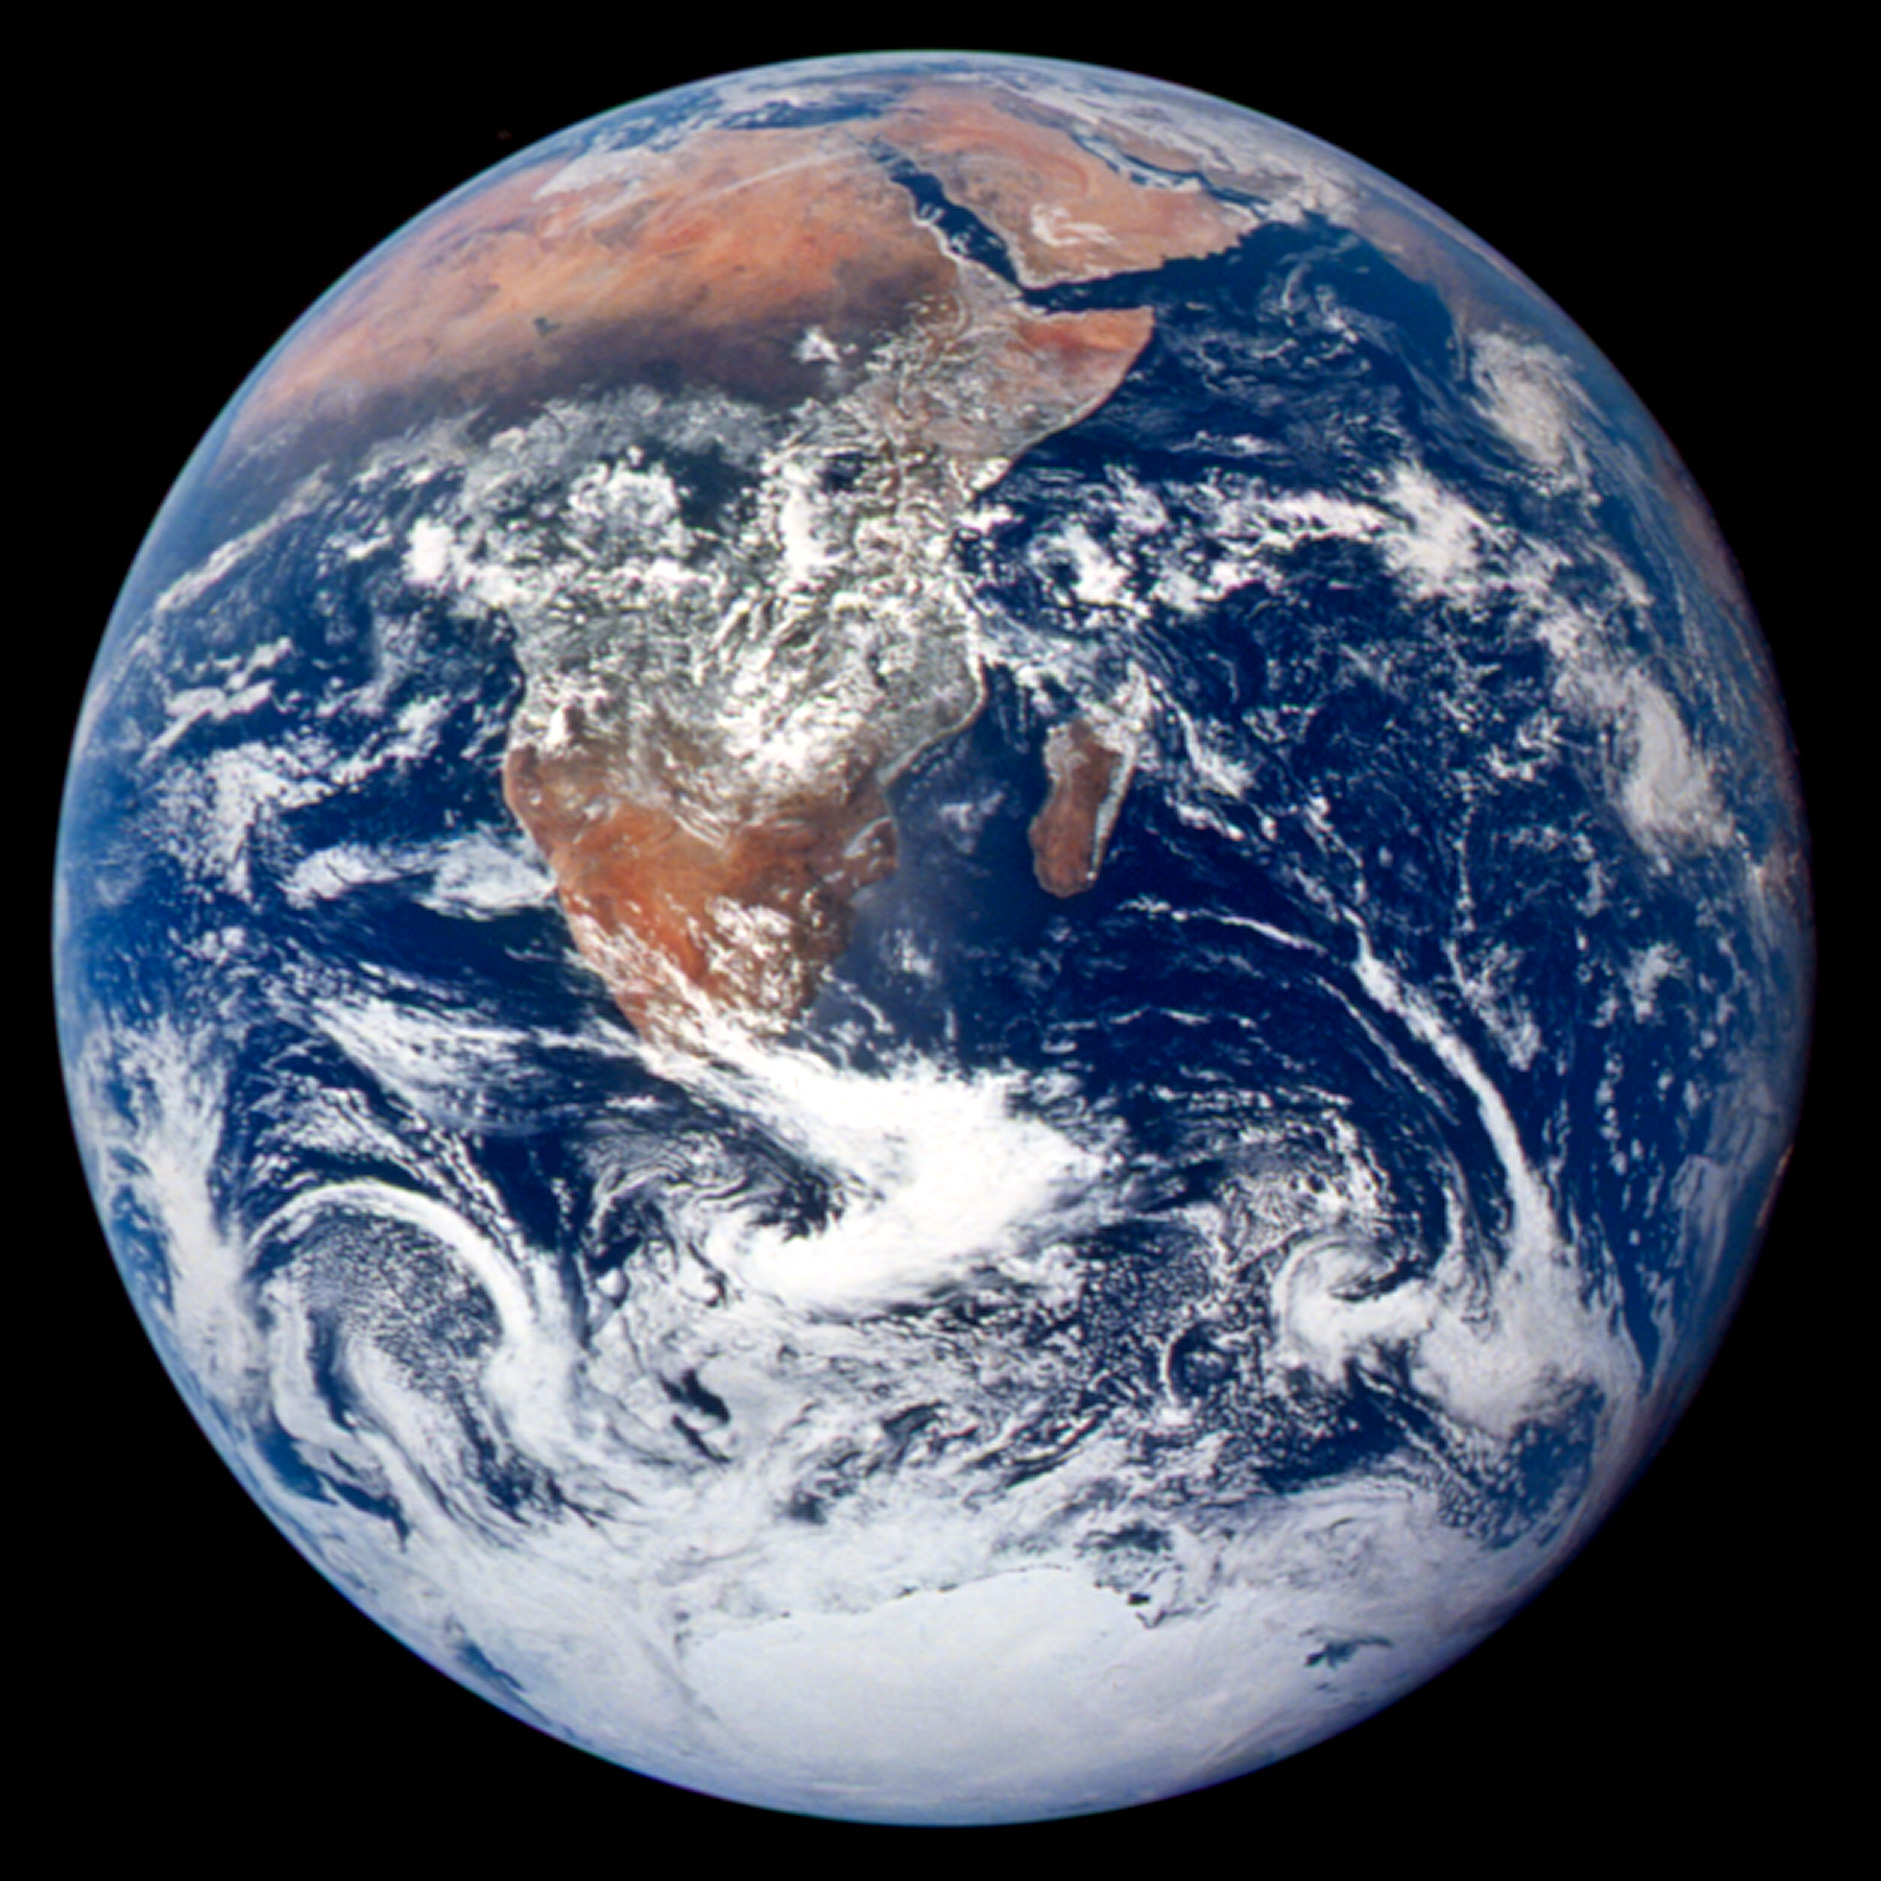
On 2 October 2026, we made one live standard image check of the NASA Apollo 17 JPEG preserved below. NASA attributes photograph AS17-148-22727 to a historical photograph taken on 7 December 1972. The submitted file is a downloaded digital reproduction, not original film or a camera RAW file.
The recorded report returned an AI-generated image signal of 6.9% and the conclusion “No strong AI finding returned”. The NASA attribution was established separately; automated public-source research was not selected. The report did not expose a detector model version.
The table and worksheet reproduce fields from the saved record. We did not run a new detector check, submit a generated counterpart or test transformed variants to prepare this guide. This single genuine-source example cannot measure missed generated images, a false-positive rate or video performance. It does not validate the product-reported accuracy figure.
| Field | Recorded value |
|---|---|
| Input | AS17-148-22727_lrg.jpg |
| SHA-256 | 83a4a11f58dc1ef12162b009c7601704f01eb96bd235a491b420265f3684998e |
| Size | 743020 bytes |
| Analysis | Standard check |
| Execution | 2026-10-02T07:50:51.663Z |
| AI-generated image signal | 6.9% · Not detected |
| Conclusion | No strong AI finding returned |
| Public-source research | not available |
Record failures, inconclusive results and reviewer outcomes separately
Copy the recorded category, signal, coverage and analysis time without inverting a percentage into a probability of authenticity. Keep automated visual observations, provenance and public-source findings distinct. A processing failure has no completed detector result; an inconclusive completed report has a result whose uncertainty matters.
Compare a frozen binary review rule with independently labelled genuine and generated inputs only where the task and label are appropriate. Count true positives, false positives, false negatives and true negatives. Sensitivity is true positives divided by all labelled generated inputs; the false-positive rate is falsely flagged genuine inputs divided by all labelled genuine inputs. Always publish those denominators.
If some results are inconclusive or unsupported, do not quietly discard them from the denominator. State the number of attempted inputs, completed reports, failures, inconclusive reports and inputs eligible for each metric. Report indeterminate cases separately. Different handling rules produce different metrics, so write the rule down first.
Record operational value beside model outcomes: whether the finding was useful to a reviewer, what additional evidence was requested, time spent and paid usage. A reviewer disposition is not automatically ground truth. Re-exporting JSON, text or PDF preserves the recorded check; a repeat analysis is a new job and may cost again.
Download the worksheet and choose a bounded next step
The blank CSV is a review worksheet for your own labels and observations. The separate NASA CSV contains exactly one recorded example; it is not a benchmark dataset or a ready-made API request. Empty cells mean unavailable or not yet assigned, not zero. The README explains the columns and counting rules.
Begin with the smallest representative set that can reveal a workflow problem. Use sandbox fixtures to test integration first, then review your selected real files in a company batch or through a live key after billing is enabled. Expand only after the error cases and spending are understood. Retention depends on the chosen workflow; keep your own authorised evidence record rather than expecting the worksheet to preserve uploaded originals.
Frequently asked questions
Does the NASA result prove the detector is accurate?
No. It is one recorded genuine-source control. It cannot measure error rates or performance on generated images, face manipulation or video.
Does the sandbox evaluate my files?
No. It returns fixed sample responses for integration tests. Real-file checks use live processing after billing is enabled.
Can I combine signal percentages across different checks?
Keep the recorded signals and their scope separate. A percentage is not a calibrated probability of fraud, and an unavailable result must not become zero.
Automated results require source and context review.
Continue with independent verification.
Test the API integration with sandbox fixturesPrimary reading
We use original standards, regulators, public institutions and research papers wherever possible. Sources were last checked on 7 October 2026.